The Success of Open Access
Open Access is in my view a success story. It seems to be fashionable to flagellate ourselves about failures to reach 100% or bumps along the way, but over the course of the last 20 years we’ve gone from a state where most of the world’s literature was not accessible to one where most of it is.
When I started my research career you had to be on campus to read. At the beginning because everything was in print, and later because that was the only place with access. Also the only place with internet access but that changed relatively quickly. Today, while I technically can log into a university network I never do. The vast majority of academic literature I want to read is accessible, and the stuff I can’t? Well it doesn’t get read most of the time.
One of the problems with framing Open Access as a success story is that you have to acknowledge the positive aspects of publishing agreements in delivery high levels of access. The reality is that the countries that provide the highest levels of access to their research outputs are the same countries that have invested heavily in publishing agreements. This has made it easy for researchers and delivered on the policy goals, but it has come at a cost.
The Financial Risks for the Future
In recent work [1] Bianca Kramer and myself have looked at the financial aspects of publishing agreements and projected forwards what those costs might look like in various contexts. We posted a preprint on the methodology and have spoken about the modelling and its consequences based on publicly available data, with a focus on Sweden and Australia. We’ve also done work using non-public data in other settings and the patterns broadly hold.
The current trajectory of publishing costs are unaffordable.
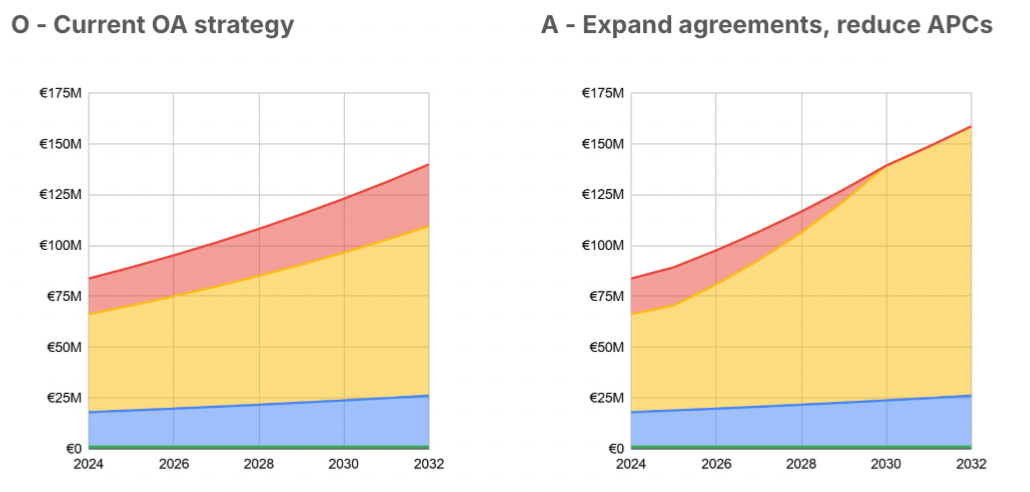
There are a couple of ways forward out of this, but in the short to medium term it seems very unlikely that publishing agreements with their current scale and scope will survive. In Sweden, which we looked at most closely, the library consortium has already signalled a shift away from agreements supporting publishing in mixed open/closed journals (“hybrid”) towards only supporting publishing in purely open access journals (“gold”). Researchers could continue to publish in the more traditional hybrid journals, but to comply with Open Access policy they would need to find the resources to pay APCs. Swedish universities have some additional funding to support this but not enough to cover the projected costs. Grants can cover some but are under significant pressure as well.
In Australia, where we also have data on the specific outputs included within agreements, we see that agreements cover virtually all the hybrid outputs, but only 10% of those in purely open access journals. As you might expect researchers appear to choose to publish in venues where their costs are covered and no additional work is required. There are no immediate plans to radically change these agreements, but with costs projected to rise the money simply isn’t there to cover the projected increases long term.
The Researcher Burden and the Structural Risk
One of the core benefits of large-scale publishing agreements has been hiding all the administrative details from researchers. Provided the system works, we don’t need to worry because everything is taken care of for us. Open Access shifts from being an agenda we were supposed to be engaged with as researchers, supporting the good of research and our communities, into background infrastructure, an invisible layer of support through which open access just happens.
What happens when that support goes away?
The most charitable projection is that researchers engage en masse and do the work, and, where necessary, provide any extra resource required, to achieve open access for their research outputs. This seems unlikely.
At the other extreme, the risk is that researchers simply continue to take the default. Large commercial publishers and the non-profit society publishers that choose to follow their lead, have consistently used default workflows to push researchers to the choices that suit the publishers’ interest. Here that will be to confront them with either paying for open access or agreeing to restrictions on repository deposit.
Dark patterns abound in journal submission workflows. Significant effort will be required to identify pathways to access and, at least based on history, the submission systems for many publishers won’t provide support.
As researchers we are both focused on the target (getting the output published) and lazy (seeking the quickest way through the submission system to achieve our goal). The likely outcome of a reduction in the scope and coverage of publisher agreements is therefore a significant, perhaps catastrophic reduction in Open Access levels.
The Repository Infrastructure and Staffing Gap
What about alternative pathways to access? In many settings rights retention and copyright exceptions are now in place, and that work continues with strong leadership from many libraries. This helps to provide the legal stability and clarity for repository deposit. In our work at COKI on citation diversity[2] we saw the suggestion that repository access is actually more strongly associated within increased citation counts and diversity. While citations are a very limited measure of use, this does suggest that utilizing repositories can provide a similar level of visibility, access and reuse as open access publishing.
But getting the appropriate version of an author’s accepted manuscript into a repository is also work, and frequently work that falls on the shoulders of one person within a university library. One consequence of the investment in publishing agreements appears to have been a lack of investment in both the technical infrastructure and staffing of repositories. There are specific local success stories and heroic efforts by many in the library system to protect, maintain and build capacity in these systems but, from the evidence we can assemble from the outside, that capacity is patchy and fragile across many countries that have invested heavily in publishing agreements. While publishing agreements have been associated with higher levels of open access publishing, the increase does not appear to flow through to overall levels of open access. Consistently we see a decrease in the proportion of outputs found only in repositories, leading overall to more modest gains in overall access levels and in some cases, no overall increase at all.
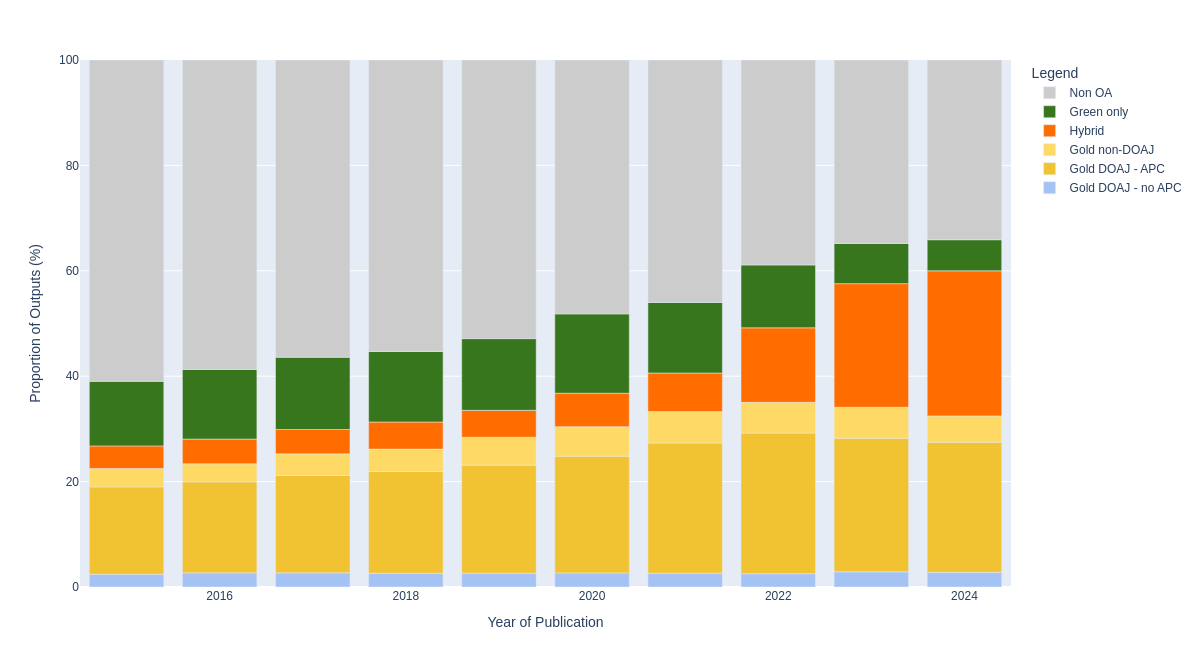
Looking more closely at repository provision we’ve also seen evidence of a lack of investment in local repository coverage at the university level. The data here is complex. The signals we see depend a lot on the technology systems for repositories and the specifics of which sites are being harvested by OpenAlex, and the extent to which this can be linked to affiliations though PIDs or URL patterns. But overall the picture is grim, with many records in repositories appearing to be metadata only and coverage of the institution’s own outputs in full text limited, even for those published Open Access under a CC BY license.

The risk
The structural risk here is that a combination of under investment in infrastructure and a focus on delivering access without requiring researcher engagement leads to a substantial backwards slide. We can make some estimates of the amount of access delivered via publishing agreements by extrapolating from the Australian and Swedish cases. A worst case scenario is agreement cancellation and no take up of the slack by researchers (and institutions) utilising and backing the capacity that is there in the library systems. The best case scenario is a mass shift by researchers to self-archiving or adoption of non-APC open access publishing venues. Neither of the extremes is likely but drops at national level in open access proportion of 10-30% are plausible.
Sweden could drop back from ~90% to 60 or 70%. Australia from around 70% back to below 50%. Extrapolating trends to other countries, the UK could drop from around 80% to 60% and the Netherlands from 90% to 70%. For the latter two interesting questions arise whether the efforts in rights retention and secondary publishing rights (led often from libraries again) and associated work will help to reduce or displace any such drop.
These are catastrophic falls. From it being a reasonable approximation that “most new scholarly content is available” we could rapidly reach a tipping point where that is no longer a viable position. In combination with the potential for financial retrenchments at large publishers as their parent companies shift away from content to whatever shiny technology they are chasing this week, or when the AI bubble bursts, the entire system is not stable.
The academic community is not well placed to weather the potential storms in front of us.
The mitigations
I would have liked to have a subject heading of “solutions” but it is perhaps better to start with mitigations of the worst consequences, with the goal that if they are well implemented they can turn into solutions over time. I also want to focus on things within the control of the academic community and research institutions today.
The key action is a re-engagement of researchers with the principle and practice of Open Access. There are real opportunities here. The AI hype has created some negative perceptions of re-use but also focused researcher attention on what we are allowed to do. Digital and online teaching has forced researchers to think about the licensing of figures we use in our lectures. The crushing weight of over-work means that the ease of access to scholarly content when at home and travelling is experienced as a massive reduction of friction.
Of course, it is easy to forget this as the grind increases and the overall experience is of a “less worse” situation. Positioning the library and information services as creating space, and if necessary in alignment with researchers over leadership is one approach that could work.
Creating that space includes making repository deposit as painless as possible. The lack of investment in repositories (and arguably the over-investment in corporate controlled, vertically integrated CRIS systems) has left deposit, and particularly mediated deposit as a painful process in most settings. This is not merely a technical investment but also crucially a staff investment. In many settings repository management has dropped in resourcing to a few FTE if not a single person. The expertise and experience of that remaining person will be critical to retraining staff, engaging researchers, and identifying improvements.
At the core this is about being serious about protecting and reinvesting the marginal savings that occur when agreements and subscriptions are cancelled, and not losing those to debt servicing and consolidated revenue. In today’s world that will be a battle, but protecting the existing budget is a starting point. Examples of reinvestment from France (at least as it was) via the Sorbonne to Tromsø offer some direction here.
Engagement programs and repository support both require resources. The challenge will be to capture resources released from agreements and ensure their reinvestment. The actual amounts needed are modest in comparison to current spend, but then they always are. Coordination across institutions also requires investment and is woefully under resourced. What coordination there is generally depends on informal networks heroically trying to hold things in alignment (you know who you are).